Flash SaleInvest in your skills
'%3E%3Cpath fill='%23CDCCD8' stroke='%23CDCCD8' stroke-linecap='round' stroke-linejoin='round' stroke-width='1.5' d='M10.5 5.5C7.2 5.5 6 6.6 6 9.63 6 6.6 4.8 5.5 1.5 5.5 4.8 5.5 6 4.4 6 1.38 6 4.4 7.2 5.5 10.5 5.5'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='a'%3E%3Cpath fill='%23fff' d='M0 0h12v11H0z'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E) Accelerate your career

 TECHADEMY
Popular & Trending
 PMIPopularProject Management Professional (PMP) Certification
 i-Hub IIT PatnaTrendingAI & Data Science Certification Program from Vishlesan i-Hub Foundation IIT Patna
 i-Hub IIT PatnaTrendingAgentic AI Program from Vishlesan i-Hub Foundation IIT Patna
 TechademyPopularCertified AI Solutions Architect
 TechademyPopularCertified AI Native Project Manager
 TechademyPopularCertified AI Native Business Analyst
Agentic AI & Data Science
i-Hub IIT PatnaTrendingAI & Data Science Certification Program from Vishlesan i-Hub Foundation IIT Patnai-Hub IIT PatnaTrendingAgentic AI Program from Vishlesan i-Hub Foundation IIT Patna TechademyBest sellerCertified Agentic AI Engineering Program
 TechademyBest sellerCertified Agentic AI No Code Bootcamp
 TechademyBest sellerAI Forward Deployed Engineer (FDE) Transition Program
 TechademyAI ML Career Transition Program
 TechademyAI ML Interview Preparation Program
Artificial Intelligence
TechademyPopularCertified AI Solutions Architect TechademyAI Mastery BootcampTechademyPopularCertified AI Native Business Analyst
 TechademyCertified AI Native Marketing Accelerator
 TechademyCertified No-Code AI DeveloperTechademyPopularCertified AI Native Project Manager
 TechademyTrendingAI Native Product Manager Transition Bootcamp
 TechademyTrendingCertified AI Native Product Manager
 TechademyPopularCertified AI Native Scrum Master
Project Management


Agile Management
 Scrum AlliancePopularCertified ScrumMaster (CSM) Training & Certification
 Scrum AllianceBest sellerCertified Scrum Product Owner (CSPO) Certification Training
 ICAgileCertified Agile Coach (ICP-ACC) Certification
 Scrum.orgProfessional Scrum Product Owner (PSPO) Certification
 Scrum.orgProfessional Scrum Master (PSM) Certification
 Scrum.orgPSM A Certification Training Course
 Scrum AllianceBest sellerA-CSPO Certification Training
 Scrum AllianceAdvanced Certified Scrum Master (A-CSM) Certification Training
 Scrum AllianceBest sellerCSP-SM Certification Training
Cyber Security


BI and Visualization


IT Service Management


Cloud Computing


'%3E%3Cpath stroke='%23CDCCD8' stroke-linecap='round' stroke-linejoin='round' stroke-width='1.5' d='M16.63 9.5c-5.23 0-7.13 1.9-7.13 7.13 0-5.23-1.9-7.13-7.12-7.13C7.6 9.5 9.5 7.6 9.5 2.38c0 5.22 1.9 7.12 7.13 7.12'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='a'%3E%3Cpath fill='%23fff' d='M0 0h19v19H0z'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E) Live AI/ML Career Program
Transition to AI/ML with a Proven Program
From Python to advanced ML, taught live by MAANG+ experts, with support for your career switch.


Looking for more details? Download Brochure'%3E%3Cpath stroke='%23fff' stroke-linecap='round' stroke-linejoin='round' stroke-width='1.5' d='M3.33 14.17v1.66A1.67 1.67 0 0 0 5 17.5h10a1.67 1.67 0 0 0 1.67-1.67v-1.66m-10.84-5L10 13.33l4.17-4.16M10 3.33v10'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='a'%3E%3Cpath fill='%23fff' d='M0 0h20v20H0z'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)
'%3E%3Cpath d='M3.07 12.87a7.5 7.5 0 1 1 13.86-5.74 7.5 7.5 0 0 1-13.86 5.74'/%3E%3Cpath d='m7.5 10 1.67 1.67 3.33-3.34'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='a'%3E%3Cpath fill='%23fff' d='M0 0h20v20H0z'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E) Up to 20 mock interviews with hiring managers and tech leadsPlacement support to help you land your ideal jobLifetime LMS access to revisit every recorded session

 36Weeks of live training
 17Weeks of interview prep
 2Capstone projects
 6Months of support


 Join 750k+ learners

' d='M7.08 1.27a.6.6 0 0 0-.5 0 1 1 0 0 0-.24.24l-.17.32-1.25 2.53-.04.08-.09.02-2.8.4-.34.06a.6.6 0 0 0-.31.16.6.6 0 0 0-.15.47c.01.14.09.24.15.31l.25.26 2.03 1.97.06.06-.02.09-.47 2.78q-.05.21-.05.35-.03.16.05.35.13.23.4.29a.6.6 0 0 0 .34-.06l.32-.15 2.5-1.32.08-.04.08.04 2.5 1.32q.18.1.32.15a.6.6 0 0 0 .35.06.6.6 0 0 0 .4-.3.6.6 0 0 0 .05-.34q-.01-.15-.05-.35L10 8.24l-.01-.09.06-.06 2.02-1.97q.15-.14.25-.26a.6.6 0 0 0 .16-.31.6.6 0 0 0-.15-.47.6.6 0 0 0-.31-.16l-.35-.06-2.8-.4-.09-.02-.04-.08-1.25-2.53-.17-.32a1 1 0 0 0-.24-.24'/%3E%3Cdefs%3E%3ClinearGradient id='a' x1='1.07' x2='12.17' y1='6.83' y2='6.83' gradientUnits='userSpaceOnUse'%3E%3Cstop offset='.68' stop-color='%23FEBC3B'/%3E%3Cstop offset='.69' stop-color='%23FEBC3B' stop-opacity='0'/%3E%3C/linearGradient%3E%3C/defs%3E%3C/svg%3E) 4.8/5 (7,900+ ratings)
Community

Standout Features of the AI/ML Program

Live Training Sessions
36 weeks of engaging, instructor-led sessions taught by seasoned MAANG+ experts.

Interview Preparation
17 weeks of focused prep to sharpen your skills and crack top AI/ML interviews.

Mock Interviews
Practice for the real thing in up to 20 mock interviews with hiring managers, tech leads and recruiters.

Capstone Projects
2 hands-on, industry-grade projects that showcase your practical AI knowledge.

AI-Powered Study Plan
A smart study plan that guides you, with a built-in coding workspace.

Extended Support
6 months of support after the program, with mentorship, doubt clearing and mock interviews.

Lifetime LMS Access
Unlimited access to all course content and recorded sessions, to review any time.

Placement Support
Help with your resume and LinkedIn profile, plus expert career coaching for the roles you want.
Meet the Team That's Invested in Your Success

Ahsan Ali

The field of AI recognizes Ahsan as one of the leading figures.
Christian Monson
Christian is a seasoned specialist with over 20 years of experience in the field of AI…

Shobhit Nigam
Shobhit brings nearly two decades of experience, having led 1500+ days of corporate…

Ashish Pal
Ashish brings over 9 years of experience in machine learning and MLOps, with a…

Francisco Garcia
With more than 13 years in machine learning, Francisco has helped push the limits…
Curriculum for Your AI/ML Transition
Ten modules: 36 weeks from Python and SQL to LLMs, agents and MLOps, then 5 weeks of DSA.

Python, SQL & Statistics (8 Weeks)
Build strong foundations in Python programming, SQL querying and key statistical concepts. Learn to write clean code, work with data structures and apply statistics to data analysis.
 Week 1: Python Basics & Programming Logic
- 1.Python setup and IDEs
- Installing Python and setting up Anaconda
- Using Jupyter, VS Code, or PyCharm
- 2.Basic syntax and indentation
- Code structure and whitespace importance
- 3.Variables and data types
- Integer, float, string, boolean
- Type checking with type()
- 4.Type casting and conversions
- Using int(), float(), str()
- 5.Basic operators
- Arithmetic: +, -, *, /, %, //, **
- Comparison: ==, !=, >, <, >=, <=
- Logical: and, or, not
- 6.Conditional statements
- Simple if
- if-else, elif
- Nested conditions
- Week 2: Loops & Functions
- 1.for and while loops
- Syntax and flow control
- Looping over ranges, lists, strings
- 2.Loop control
- break, continue, pass
- 3.Function definition and syntax
- def keyword, indentation, naming
- 4.Parameters and return values
- Positional and keyword arguments
- 5.Lambda functions
- Anonymous functions
- When and how to use
- 6.Recursion
- Concept and examples
- Base and recursive cases
- Week 3: Python Data Structures Deep Dive
- 1.Lists
- Creation, indexing, slicing
- Methods: append, extend, insert, remove
- 2.Tuples
- Immutability and packing/unpacking
- 3.Sets
- Unique values, operations: union, intersection
- 4.Dictionaries
- Key-value access, get(), items(), values()
- 5.List comprehensions
- Syntax and performance benefits
- 6.Iteration tools
- enumerate(), zip(), map(), filter()
- Week 4: File Handling, Modules & Error Handling
- 1.File I/O
- Reading and writing text files
- Working with CSV using csv module
- Reading JSON using json module
- 2.Working with OS and paths
- os, pathlib
- 3.Importing modules
- Standard libraries: math, datetime, random
- Installing third-party packages
- 4.Custom modules
- Creating and importing user-defined modules
- 5.Error types
- Syntax vs. runtime errors
- 6.Try-except blocks
- Handling exceptions gracefully
- 7.Finally, raise, and custom exceptions
- Week 5: SQL for Data Science – Part 1
- 1.Relational database concepts
- Tables, rows, columns, keys
- 2.SELECT queries
- Syntax, selecting multiple columns
- 3.Filtering with WHERE
- Operators: =, >, <, BETWEEN, IN, LIKE
- 4.Sorting with ORDER BY
- ASC, DESC
- 5.Grouping with GROUP BY and HAVING
- Aggregate functions: COUNT, SUM, AVG, MIN, MAX
- Week 6: SQL: Joins, Subqueries, Window Functions – Part 2
- 1.Joins
- INNER JOIN
- LEFT, RIGHT, FULL OUTER JOIN
- 2.Subqueries
- Inline subqueries
- Correlated subqueries
- 3.Window functions
- ROW_NUMBER, RANK, DENSE_RANK
- LAG, LEAD for time-based analytics
- 4.Indexing and optimization
- Primary vs. secondary indexes
- Query performance tips
- Week 7: Descriptive Statistics & Probability
- 1.Measures of central tendency
- Mean, median, mode
- 2.Measures of dispersion
- Range, variance, standard deviation, IQR
- 3.Probability basics
- Sample space, events
- Probability rules
- 4.Conditional probability
- Bayes’ Theorem
- 5.Law of Large Numbers
- 6.Central Limit Theorem
- Week 8: Distributions, Hypothesis Testing & Inference
- 1.Probability distributions
- Normal, Binomial, Poisson
- 2.Sampling techniques
- Random, stratified, systematic
- 3.Hypothesis testing
- Null vs. alternative hypothesis
- 4.Statistical tests
- t-tests, z-tests
- ANOVA, chi-square
- 5.Significance and p-values
- 6.Confidence intervals
Data Processing (3 Weeks)
Master NumPy and Pandas for data manipulation. Learn to clean, transform and prepare real-world data for deeper analysis and machine learning.
- Week 9: NumPy & Pandas
- 1.NumPy arrays
- Creating, indexing, reshaping
- 2.Vectorized operations
- Broadcasting, element-wise ops
- 3.Pandas DataFrames
- Creating from dicts, CSV
- 4.Series vs. DataFrames
- 5.Indexing and filtering
- loc, iloc, boolean indexing
- 6.Handling missing values
- 7.Aggregations with groupby
- 8.Merging and concatenating
- Week 10: EDA & Data Cleaning
- 1.Handling missing values
- Drop, fill, interpolation
- 2.Outlier detection
- Boxplots, Z-scores, IQR
- 3.Data type conversion
- astype()
- 4.Visual exploration
- histograms, boxplots, pairplots
- 5.Correlation matrix
- Heatmaps
- 6.Value counts and frequencies
- Week 11: Feature Engineering & Data Preprocessing
- 1.Data imputation
- Mean/median/mode imputation
- KNN imputer, iterative imputer
- 2.Feature scaling
- MinMaxScaler, StandardScaler, RobustScaler
- 3.Encoding categorical variables
- One-Hot Encoding, Label Encoding, Ordinal Encoding
- 4.Feature selection
- Variance Threshold, SelectKBest
- Recursive Feature Elimination (RFE)
- 5.Dimensionality Reduction
- Principal Component Analysis (PCA)
- Interpretation of principal components
Core ML: Supervised & Unsupervised (4 Weeks)
Understand the fundamentals of supervised learning, model building and evaluation. Gain hands-on experience with regression, classification and model tuning.
- Week 12: Intro to ML + Evaluation Metrics
- ML lifecycle and workflow
- Types of learning: supervised, unsupervised, reinforcement
- Train/test/validation split
- Overfitting vs. underfitting
- 1.Bias-variance trade-off
- Classification metrics
- 2.Accuracy, Precision, Recall, F1 Score
- Regression metrics
- MSE, RMSE, MAE, R-squared
- ROC Curve and AUC
- Confusion matrix
- Week 13: Regression Models
- Linear regression
- 1.Line fitting, coefficients, intercept
- 2.R-squared and adjusted R-squared
- Polynomial regression
- 1.Curve fitting, overfitting prevention
- Regularized regression
- 1.Ridge regression (L2)
- 2.Lasso regression (L1)
- 3.ElasticNet (combined L1 and L2)
- Multicollinearity
- 2.Variance Inflation Factor (VIF)
- Residual diagnostics
- 1.Plotting and interpretation
- Week 14: Classification Models
- 1.Logistic Regression
- Odds, log-odds, sigmoid function
- 2.Decision Trees
- Gini impurity, entropy, information gain
- Pruning, depth control
- 3.Random Forest
- Ensemble of trees, bagging technique
- Feature importance extraction
- 4.Support Vector Machine (SVM)
- Linear and kernel-based SVM
- Hyperplane, margin, slack variable
- 5.Model interpretability
- Confusion matrix and classification report
- Week 15: Hyperparameter Tuning & Cross-validation
- 1.Cross-validation
- Importance and types (Holdout vs. K-Fold)
- 2.K-Fold, StratifiedKFold
- How K-Fold splits data
- Preserving class ratios with StratifiedKFold
- 3.GridSearchCV
- Defining parameter grid
- Finding the best parameter set
- 4.RandomizedSearchCV
- Sampling parameters randomly
- Speed vs. coverage trade-off
- 5.Imbalanced Data Techniques
- SMOTE for oversampling
- Undersampling basics
- 6.Final Model Selection & Evaluation
- Compare models using CV scores
- Select based on accuracy, F1, or AUC
Unsupervised Learning & Recommenders (3 Weeks)
Explore clustering, anomaly detection and recommendation systems. Learn to uncover hidden patterns and personalize user experiences with data.
- Week 16: Clustering Techniques
- 1.K-Means
- Initialization, choosing K
- Elbow method and Silhouette score
- 2.Hierarchical clustering
- Agglomerative, divisive methods
- Dendrogram interpretation
- 3.DBSCAN
- Density-based clustering
- Noise and outlier detection
- Week 17: Dimensionality Reduction & Anomaly Detection
- 1.Dimensionality Reduction
- PCA (Principal Component Analysis)
- Variance explanation
- Scree plots
- LDA (Linear Discriminant Analysis)
- Supervised dimensionality reduction
- t-SNE (t-distributed Stochastic Neighbor Embedding)
- Nonlinear dimensionality reduction for visualization
- UMAP (Uniform Manifold Approximation and Projection)
- Manifold learning and low-dimensional embedding
- 2.Anomaly Detection
- Statistical Methods
- Z-score method
- Interquartile Range (IQR)
- Isolation Forest
- Anomaly scoring using random partitioning trees
- One-Class SVM
- Support vector boundary-based anomaly detection
- Application Scenarios
- Fraud detection
- Network security
- Quality control in manufacturing
- Week 18: Recommender Systems
- 1.Types of Recommender Systems:
- Content-based filtering
- Collaborative filtering (user-based, item-based)
- 2.User-Item Matrix Representations:
- Cosine similarity
- Pearson correlation
- 3.Matrix Factorization Techniques:
- Singular Value Decomposition (SVD)
- Non-negative Matrix Factorization (NMF)
- 4.Association Rule Mining:
- Apriori algorithm
- FP-Growth algorithm
- 5.Evaluation Metrics:
- RMSE (Root Mean Squared Error)
- Precision@K
- Recall@K
Deep Learning (9 Weeks)
Dive into neural networks and advanced architectures like CNNs and GANs. Apply deep learning to images, text and generative tasks through real-world projects.
- Week 19: Neural Networks & MLPs
- 1.Perceptron and MLP
- 2.Forward and Backpropagation
- 3.Loss functions
- MSE, Cross-Entropy
- 4.Optimizers
- SGD, Adam, RMSprop
- 5.Activation Functions
- ReLU, Sigmoid, Tanh, Softmax
- 6.Regularization
- Dropout, BatchNorm
- Week 20: CNNs
- 1.Convolution operation
- 2.Filters and feature maps
- 3.Pooling layers
- 4.CNN architectures
- LeNet, VGG, ResNet
- 5.Transfer learning
- Fine-tuning pre-trained models
- 6.Image classification project
- Week 21: Generative Deep Learning Models
- 1.Autoencoders (AEs)
- Encoder-decoder structure
- Bottleneck representation
- Applications: Denoising, dimensionality reduction
- 2.Variational Autoencoders (VAEs)
- Probabilistic latent space
- KL divergence and reconstruction loss
- Sampling with reparameterization trick
- 3.Generative Adversarial Networks (GANs)
- Generator and discriminator roles
- Loss functions and training dynamics
- Common issues: mode collapse, instability
- 4.U-Net Architecture
- Encoder-decoder with skip connections
- Applications in biomedical and satellite image segmentation
- Dice coefficient and IoU evaluation
- 5.Diffusion Models
- Forward (noise) and reverse (denoise) processes
- Intuition behind denoising diffusion probabilistic models (DDPMs)
- Recent advances: DALL·E 2, Stable Diffusion
- Week 22: Foundations of Text-to-Image Models & Vision-Language Alignment
- 1.Introduction to Text-to-Image Models
- Evolution from GANs to diffusion models
- Applications in design, marketing, and synthetic data generation
- 2.CLIP (Contrastive Language–Image Pre-training)
- Contrastive learning between images and text
- Architecture and embedding space alignment
- CLIP’s role in guiding image generation
- 3.DALL·E & DALL·E 2
- Overview of the transformer-based architecture
- Text-to-image and inpainting use cases
- Concept of zero-shot and few-shot generation
- Week 23: Diffusion-Based Architectures, Prompt Engineering & Practical Implementation
- 1.Imagen (Google)
- T5-based text encoding and cascaded diffusion
- High-fidelity generation and FID score performance
- Human preference comparisons with DALL·E
- 2.Stable Diffusion
- Latent diffusion models (LDMs)
- UNet, Variational Autoencoders, CLIP conditioning
- Architecture breakdown and hands-on usage
- 3.Prompt Engineering
- Crafting prompts for specific image outcomes
- Controlling prompt weight and image style
- Multi-modal prompts and stylistic augmentation
- Week 24: NLP Pipeline, Preprocessing & Text Representation
- 1.NLP Pipeline Overview
- Stages: text preprocessing → feature extraction → modeling
- Applications: chatbots, search engines, auto-summarization
- 2.Text Preprocessing
- Word and sentence tokenization
- Stopword removal techniques
- Stemming (Porter) and Lemmatization (WordNet)
- 3.Text Representation Techniques
- Bag-of-Words (BoW)
- TF-IDF: concept, formula, and practical use
- Introduction to embeddings (Word2Vec, GloVe — conceptual)
- Week 25: Core NLP Tasks, Traditional Models & Evaluation
- 1.Basic NLP Tasks
- Sentiment Analysis
- Text Classification using labeled datasets
- Named Entity Recognition (NER) overview
- 2.Traditional Models for NLP
- Naive Bayes for spam/sentiment classification
- Logistic Regression for binary/multi-class classification
- SVM: kernel-based text classification
- 3.Evaluation Metrics for NLP Models
- Confusion matrix interpretation
- Precision, Recall, F1-score for unbalanced datasets
- Macro vs. micro averaging in multi-class problems
- Week 26: Word Embeddings & Foundations of Neural NLP
- 1.Word Embeddings
- Word2Vec, GloVe, nn.Embedding
- Concept of similarity in vector space
- Static vs. contextual embeddings
- Limitations: context-agnostic, rare/unknown words
- 2.Feed-Forward Networks for Text
- Using TF-IDF or averaged embeddings as inputs
- Basic dense architectures for classification/regression
- Limitations: no order or syntax awareness
- 3.Recurrent Neural Networks (RNNs)
- Sequence modeling using hidden states
- Maintaining memory across steps
- Limitations: vanishing gradients, parallelization issues
- Week 27: LSTM, GRU & Sequence-Based NLP Applications
- 1.Long Short-Term Memory Networks (LSTMs)
- Cell states, forget/input/output gates
- Handling long-term dependencies
- Bidirectional LSTM for richer context
- Limitations: slower training, sequential processing
- 2.Gated Recurrent Units (GRUs)
- Update and reset gates
- Parameter efficiency and faster convergence
- Performance trade-offs with LSTM
- 3.NLP Applications Using RNN-Based Models
- Sentiment classification with LSTM or GRU
- Named Entity Recognition with BiLSTM/GRU
- Character-level RNNs for text generation
LLMs & Generative AI (4 Weeks)
Explore how large language models work and how to design effective prompts. Build practical applications with HuggingFace, RAG systems and vector stores.
- Week 28: Transformers & LLM Foundations
- 1.Transformers & Attention Mechanism
- Attention mechanism
- Scaled dot-product attention
- Self-attention vs. cross-attention
- Multi-head attention
- Positional encoding
- Transformer architecture: Encoder-decoder structure
- 2.LLMs & HuggingFace
- Transformer models overview: GPT, BERT, T5, etc.
- Tokenization techniques: WordPiece, Byte-Pair Encoding
- Embeddings: static vs. contextual embeddings
- HuggingFace basics:
- 1.Pipelines for NLP tasks
- 2.Model hub exploration
- Fine-tuning for sentiment analysis and classification
- Week 29: Prompt Engineering Basics
- 1.Foundations of Prompting & Design
- Introduction to Prompt Engineering
- 1.Prompts as a way to program LLMs
- 2.Use cases: chatbots, summarization, classification, code generation
- 2.Prompting Strategies
- Zero-shot prompting: direct queries without examples
- Few-shot prompting: adding labeled examples
- Chain-of-thought prompting: guiding step-by-step reasoning
- 3.Prompt Design Best Practices
- Writing clear and unambiguous instructions
- Setting context: tone, persona, formatting
- Output constraints: length, style, structure
- Reducing hallucinations and ambiguity
- Week 30: Prompt Chaining, Tool Augmentation & RAG Foundations
- 1.Prompt Chaining & Structured Workflows
- Sequential and modular task execution
- Multi-step reasoning, report generation, agents
- 2.Tool-Augmented Prompting
- LLMs calling tools or APIs using function-calling/plugins
- LangChain/AutoGPT pipelines with dynamic prompt generation
- Incorporating retrieved context using vector stores (RAG)
- 3.Debugging and Evaluating Prompts
- Identifying vague prompts vs. precise prompts
- Tuning temperature, max tokens, system/user role formatting
- Performing A/B testing with prompt phrasing and sampling
- 4.Why RAG?
- Hallucination problems in LLMs
- Role of retrieval in grounding LLM responses
- External knowledge sources (FAQs, PDFs, sites)
- 5.RAG Architecture & Workflow
- Retriever-Generator architecture
- End-to-end pipeline: User Query → Embed → Retrieve → Prompt → LLM Output
- 6.Document Ingestion & Chunking
- Loading data from multiple sources (PDFs, Notion, HTML)
- Recursive text chunking and overlapping windows
- Metadata tagging: title, source, URL, date
- 7.Embedding & Vector Stores
- Generating embeddings: OpenAI, HuggingFace, Cohere
- Storing and querying using FAISS or Chroma
- Cosine similarity and other distance metrics
- Week 31: Prompt Integration, RAG System Design & Deployment
- 1.Prompt Construction for RAG
- Techniques to inject retrieved chunks into LLM prompts
- Formatting strategies: summaries, bullet points, citations
- Handling token limits in long contexts
- 2.Tools & Libraries for RAG
- LangChain: Chains, Retrievers, Memory, PromptTemplates
- OpenAI/HuggingFace RAG pipelines
- Optional: LLamaIndex for lightweight use cases
- 3.UI Layer: Prototyping a RAG Assistant
- Build a Streamlit/Gradio app with RAG backend
- Allow real-time querying with source-grounded answers
- Display retrieved documents with model response
Agentic AI & Automation (2 Weeks)
Discover how autonomous agents use tools and memory to complete tasks. Build multi-step workflows with LangChain and explore real-world automation use cases.
- Week 32: Agents & LangChain Workflows
- 1.What is an Agent?
- Definition and real-world analogy of an autonomous AI agent
- Difference between tools, chains, and agents in LangChain
- 2.LangChain Architecture
- Key components: Prompts, Models, Memory, Chains, Tools
- How LangChain manages conversational context
- 3.Tools, Chains, and Memory
- Tool calling with APIs (e.g., calculator, web search)
- Memory management (Buffer, Summary, EntityMemory)
- Creating reusable chains for tasks
- 4.Multi-step Reasoning
- Agent workflows that solve complex problems
- Using ReAct (Reason + Act) pattern in LangChain
- 5.Planning and Tool Usage
- How agents decide which tools to use and when
- Example: Step-by-step decision making with intermediate steps
- Week 33: AutoGPT & Task Automation
- 1.Intro to AutoGPT
- Overview of autonomous AI loops
- 2.Prompt Chaining and Formatting
- Sequential prompt design
- Intermediate result reuse
- 3.Workflow Automation
- Task breakdown
- Self-directed task loops and memory integration
- 4.Use Cases
- Marketing automation
- Data analysis
- Report generation
- Automated data pipeline orchestration
Reinforcement Learning (1 Week)
Understand how agents learn through trial and error using rewards. Learn Q-learning and deep reinforcement learning, with applications in games and robotics.
- Week 34: Reinforcement Learning (Fundamentals & Deep RL)
- RL Fundamentals
- MDP formulation: State, Action, Reward, Policy
- Exploration vs. exploitation
- ε-greedy strategy
- Q-Learning and Q-table updates
- Deep Reinforcement Learning
- 1.Deep Q Networks (DQN)
- Experience replay
- Target network
- 2.Actor-Critic Models
- Advantage Actor Critic (A2C)
- Applications
- Games
- Robotics
- Trading
MLOps & Deployment (2 Weeks)
Learn to track experiments, version models and monitor ML systems. Get hands-on with APIs, Docker and cloud deployment to put your models into production.
- Week 35: MLOps Fundamentals
- 1.ML system lifecycle overview
- 2.CI/CD principles for ML
- 3.Experiment tracking
- 4.MLflow basics: tracking, models, UI
- 4.Model versioning
- 5.Registering and managing models
- 6.Model and data drift
- Monitoring strategies
- Week 36: Model Deployment
- 1.Flask & FastAPI
- Creating APIs for models
- Route setup and JSON responses
- 2.Serialization
- Pickle, Joblib for saving models
- 3.Docker
- Containers, Dockerfile, docker-compose
- 4.Cloud deployment basics
- AWS S3, EC2, Lambda
- GCP: Cloud Run, AI Platform
- 5.Monitoring deployed models
- Logging and alerting basics
Data Structures & Algorithms (DSA) (5 Weeks)
Master core data structures and algorithm paradigms through efficient problem-solving: sorting, recursion, backtracking, trees, graphs and dynamic programming.
- Week 37: Sorting & Algorithm Foundations
- Introduction to sorting algorithms
- Basics of asymptotic analysis (Big O, Theta, Omega)
- Worst-case and average-case time complexity
- Sorting algorithms: Bubble, Selection, Insertion, Merge, Quick, Heap
- Algorithm paradigms: Divide & Conquer, Decrease & Conquer
- Presorting and its applications
- Merge sort on linked lists, 3-way quicksort
- Week 38: Recursion & Backtracking
- Recursion basics: base case, recursive case
- Recursive mathematical problems (factorial, Fibonacci)
- Combinatorial enumeration (nCr, permutations)
- Exhaustive enumeration with backtracking
- Letter case permutations, combinations, subsets
- Sudoku solver, N-Queens, Rat in a Maze
- Week 39: Trees & Hashing
- Binary Search Trees (BST): insert, search, min/max
- Dictionaries & hash tables: collision resolution, load factor
- Tree traversals: Inorder, Preorder, Postorder
- Level order traversal (BFS), DFS on trees
- BST problems: Diameter, Count Univalue Subtrees, Lowest Common Ancestor
- Tree construction from traversal arrays
- Week 40: Graphs & Connectivity
- Graph types: directed, undirected, weighted
- Representation: adjacency list, matrix, edge list
- BFS and DFS traversal
- 7 Bridges of Königsberg and Eulerian paths
- Stack-based DFS and recursion-based DFS
- Finding connected components
- Graph problems: bipartite check, cycle detection, topological sort
- Week 41: Dynamic Programming (DP)
- Principles of DP: overlapping subproblems, optimal substructure
- Top-down (memoization) vs bottom-up (tabulation)
- Classic problems: Climbing Stairs, Subsets of size k
- DP on grids: Unique paths, obstacles, path sums
- Coin Change, Edit Distance, Word Break, Equal Subset Partition
System Design (3 Weeks)
Build a strong foundation in system design to approach open-ended design interviews with confidence: distributed systems, databases, caching and cloud-native trade-offs.
- Client-server model basics
- Web server architecture and request lifecycle
- Cryptographic hash functions and hashing index
- CAP theorem, caching strategies, storage engines
- Load balancing strategies: round-robin, consistent hashing
- Database replication and failover mechanisms
- Network protocols (TCP, HTTP/2, HTTPS)
- Week 43: Batch Processing Systems Topics Covered:
- Inverted Index & search engine architecture
- K-way merge sort for external sorting
- Distributed file systems (HDFS, S3)
- MapReduce paradigm and Hadoop architecture
- Data flow vs control flow in batch jobs
- Graph processors for analytics (e.g., Pregel)
- Designing recommendation systems and typeahead suggestions
- Week 44: Stream Processing & Real-Time Systems Topics Covered:
- Event-driven architectures and real-time analytics
- Application performance monitoring tools (APM)
- Architecture for live video broadcasting (YouTube Live, Twitch)
- Real-time map rendering (e.g., Google Maps)
- Windowing and checkpointing in stream processing (Apache Flink, Kafka Streams)
- Trade-offs in stream vs. batch processing
AI/ML Domain (7 Weeks)
Build, evaluate and deploy machine learning models with Python and SQL, then master deep learning, AI system architecture and frameworks like transformers and LangChain.
- Week 45: Python, Data Handling & SQL Review
- Python syntax, control flow, data structures
- List/dict/set comprehensions, lambda/map/filter
- NumPy and Pandas for transformations, filtering, aggregation
- SQL: Joins, subqueries, aggregations, window functions
- Practice: Python/SQL Leetcode problems and data analysis mini tasks
- Week 46: Machine Learning Fundamentals & Evaluation
- ML workflow: data prep, modeling, evaluation
- Overfitting/underfitting, bias-variance trade-off
- Classification vs regression, label encoding, scaling
- Metrics: accuracy, precision, recall, F1, ROC-AUC, RMSE
- Practice: Run basic classification/regression models using scikit-learn
- Week 47: Feature Engineering, Model Tuning & Explainability
- Feature engineering: imputation, encoding, PCA, RFE
- Cross-validation strategies: K-Fold, StratifiedKFold
- Hyperparameter tuning: GridSearchCV, RandomSearchCV
- Explainability tools: SHAP, LIME
- Practice: Evaluate different ML models using a real dataset
- Week 48: Advanced ML – Trees, Ensembles & Imbalanced Data
- Decision Trees, Random Forests, SVM
- Boosting algorithms: XGBoost, LightGBM, CatBoost
- Class imbalance: SMOTE, ADASYN, ensemble tuning
- Model comparison using cross-validation + metrics
- Practice: Case study — build and evaluate a fraud detection model
- Week 49: Deep Learning, Transformers & Generative AI
- Neural nets: MLPs, CNNs, RNNs — architecture & use cases
- Transformers: attention, encoder-decoder, self-attention
- LLMs: GPT vs BERT, tokenization, fine-tuning with HuggingFace
- RAG architecture with FAISS/Chroma vector DBs
- Practice: Build a basic chatbot or classification model using a pre-trained LLM
- Week 50: Agentic AI & LangChain Workflows
- LangChain architecture: prompts, chains, tools, agents
- AutoGPT basics and planning tools
- Integrating tools with memory and context
- LangChain-based multi-step agent projects
- Practice: Implement a use-case like automated research assistant or data pipeline explainer
- Week 51: ML System Design & AI Architecture
- ML system design principles: modularity, scalability, latency
- Components: data ingestion, processing, feature store, model registry, deployment, monitoring
- Deployment patterns: batch vs. real-time, CI/CD, containerization (Docker)
- LLM & RAG system architecture: vector store, retriever, generator
- Practice: Design prompts like:
- "Build a recommendation system for an e-commerce platform"
- "Design a pipeline to retrain a fraud detection model every week"
- "How would you productionize a ChatGPT-like solution for a bank?"

Testimonials from Career Switchers
What learners from analytics, software, QA and engineering backgrounds say about the program.

From Numbers to Neural Networks!
Honestly before taking this program I doubted if I could ever switch from analytics to machine learning but the program made me realize my potential and helped me transition into AI and ML. The way the trainers explain concepts and the projects we worked on helped me alot. The mentorship kept me going when I felt stuck, and I’m now working as an ML Engineer!

This Program Was a Turning Point
I spent numerous years trapped in my BI career and wanted to grow. This program provided insights that went beyond acquiring new technical abilities because it restructured how I approached things. Instead of traditional teaching methods the mentors exposed students to genuine field experience. I’ve never felt more confident in my skills.

Finally, a Program That Gets It Right
The course teaching methods stood out from all other courses I had taken. It was real interaction, real assignments, and real feedback from the FAANG experts. Every session created a new wave of confidence within me. I walked into interviews knowing exactly what to expect and how to handle it smartly.

I Was Interview-Ready Way Sooner Than I Expected
I didn’t come from a strong coding background, but the way this program breaks things down was a game-changer. The mock interviews, feedback, and one-on-one sessions made all the difference. I finally cracked interviews that had once felt out of reach.

A Complete Shift—And It Was Worth It
Transitioning from engineering to AI proved difficult, but I found the perfect roadmap and training here. The instructors were full of knowledge, interactive and understood what beginners need. They focused on clarity and delivered their content in plain language instead of technical terms, so it’s easy for beginners to understand. And now I’m doing machine learning work I used to only read about.

 Google
 Trustpilot
 Course Report
Book a Free 15-Minute Call with a Career Advisor
Still unsure if this training is right for you? Our expert career advisors are just one click away.
What you will learn
Six skill sets across the ML lifecycle, from Python and data to deep learning, LLMs and MLOps.
Programming & Dev Environments
Hands-on Python 3 for ML, DL, LLMs, and scripting using Jupyter, Colab, VS Code, and the terminal.
Data Handling, Visualization & SQL
Clean and analyze data with Pandas and NumPy, process images with OpenCV, and create visuals with Matplotlib, Seaborn and Plotly. Query SQLite or PostgreSQL, and manage databases in DB Browser and pgAdmin.
Statistics & Machine Learning
Apply SciPy for statistical tests and optimization. Build models with scikit-learn, XGBoost, LightGBM and CatBoost, handle imbalance with imbalanced-learn, and explain predictions with SHAP and LIME.
Deep Learning
Develop models with TensorFlow and Keras. Use PyTorch for advanced projects and for fine-tuning models like ResNet.
NLP, Transformers & LLMs
Work with Hugging Face, BERT, GPT and custom tokenizers. Build retrieval systems using FAISS and ChromaDB.
MLOps, Deployment & Automation
Track models with MLflow and package them with Docker. Deploy with Flask or FastAPI, test with Postman, and manage code with Git and GitHub.
Eligibility

Prerequisites for the AI/ML Career Transition Program

No ML background is needed, and basic coding in any language is a plus but not mandatory.
A STEM or tech background is a good fit: software engineers, data scientists, MLOps, DevOps, backend and cloud roles, and MS or PhD researchers.
Classes run on Sundays, 9 AM to 1 PM PST and Thursdays, 6 to 8 PM PST, with doubt clearing on Tuesdays, 6 to 8 PM PST.
This program is for you
For developers, IT pros and anyone from tech or STEM aiming for roles like AI, Computer Vision or MLOps Engineer.
Software Developers Ready for AI/ML
IT Pros Craving AI Innovation
Anyone from Tech Background
Anyone from STEM Background
Data Scientists Scaling Up ML Skills
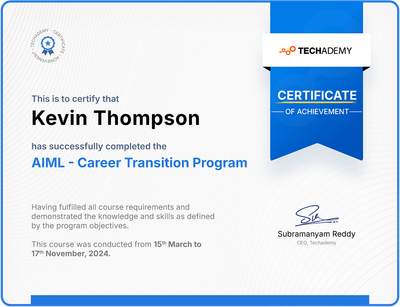
Earn the AI/ML Credential
Build industry-relevant AI skills
Learn advanced machine learning, deep learning and large language models through hands-on practice.
Gain credibility with a respected certificate
Receive a shareable, verifiable credential that validates your skill in building intelligent, scalable systems.
Step into high-demand AI roles
Qualify for roles like ML Engineer, Data Scientist, AI Consultant and NLP Engineer, with skills in modeling and deployment.
Certification
Want all of this in one file?
The week-by-week curriculum, the schedule and the fee, as a PDF you can read offline or forward to whoever signs it off.
Learn the Core AI Tools of the ML Lifecycle
Knowing algorithms is not enough. Employers want people who can use real tools to build models, deploy pipelines and manage ML systems at scale. That is why the program trains you, hands-on, on the most in-demand tools, from data wrangling to deployment.
An Award Winning End-to-End Talent Solutions
Our cutting-edge platform empowers businesses to strategically hire, develop, and retain top talent.
Industry-standard tools
Gain proficiency in industry-standard AI and ML tools.

Model deployment
Learn to manage models and deploy them into production.
Best practices
Empower your team with best practices and the latest tools.
In-role productivity
Boost in-role productivity with new skills.
Frequently Asked Questions
01What is the Interview Process Like for Machine Learning Roles at MAANG+ and Tier-1 Companies?
The Machine Learning interview process at top tech companies generally includes multiple stages designed to assess your technical, analytical, and behavioral fit. Here's a breakdown of what to expect: 1. Initial Technical Screening Format: Phone or virtual interview
Focus Areas:
- Basic understanding of Machine Learning concepts
- Discussion of past ML projects
- Coding problems (often LeetCode medium to hard level)
2. Core Technical Rounds (On-site or Virtual – 3 to 8 Rounds)
a. Coding Rounds (1–2 rounds)
- Data Structures and Algorithms
- ML-specific coding tasks
- In-depth ML project discussions
b. System Design Rounds (1–2 rounds)
- Scalable software system design
- ML system design (e.g., building a recommendation engine)
- Note: For candidates with <3 years of experience, ML system design may be replaced with an additional ML fundamental round.
c. ML Technical Rounds (1–3 rounds)
- Breadth and depth of ML understanding
- Topics include:
- Linear/Logistic Regression
- Decision Trees, SVM, Neural Networks
- Optimization techniques (e.g., Gradient Descent)
- Loss functions (e.g., Cross-Entropy Loss)
- Tools and deployment pipelines
3. Behavioral Round
- Experience and project-based discussion
- Open-ended questions to assess cultural and team fit
Summary
Candidates should prepare for:
- Strong coding and DSA skills
- A solid grasp of ML algorithms and system-level thinking
- The ability to explain and discuss past ML projects
- Clear communication and alignment with company values during behavioral interviews
01What are the most asked interview questions for Machine Learning roles at top tech companies?
1. Coding & Algorithmic Questions Expect questions that test your data structures, algorithms, and ability to translate ML problems into code.
- Implement a word segmentation algorithm: Given a string without spaces, recover the original sentence using a valid dictionary.
- Given a list of timestamps and user IDs, find the longest active streak for each user.
- Given a binary tree, write a function to return the path with the maximum sum passing through the root.
- Implement K-means clustering using only NumPy (no scikit-learn).
- Write a function to apply a convolution operation on a grayscale image matrix. Extend it with stride and padding options.
- Design a scheduler to assign jobs across machines with varying CPU & RAM capacities.
2. System Design for ML These questions evaluate your ability to build scalable and efficient ML-powered systems.
- Design a movie recommendation engine for an in-flight entertainment system.
- Architect a system for real-time fraud detection for an e-commerce platform.
- Design a scalable ML pipeline to personalize news feed content.
- How would you build a trigger word detection system like “Hey Google”?
- Explain how you’d design an ML feature store and manage feature versioning.
3. Core ML Conceptual Questions These test your understanding of fundamental algorithms, optimization techniques, and practical trade-offs.
- What’s the difference between bias-variance tradeoff and overfitting-underfitting?
- Explain how you’d handle imbalanced datasets in classification problems.
- How does dropout prevent overfitting in neural networks?
- What is the vanishing gradient problem, and how can it be mitigated?
- When should you use precision over recall in a classification task?
- Why might XGBoost outperform logistic regression or SVM on tabular data?
4. ML Tools, Frameworks, and Deployment Companies often assess your familiarity with the real-world tech stack.
- Describe how you’d deploy a model using Docker and Kubernetes.
- What are the pros and cons of using batch inference vs. real-time inference?
- How do you monitor model drift in production?
- Explain the differences between TF Serving, TorchServe, and BentoML.
- What CI/CD practices would you follow for ML systems?
5. Open-ended & Behavioral ML Questions These assess your ability to think holistically, collaborate cross-functionally, and contribute meaningfully to business impact.
- Pick a product you love and describe how you’d improve it using ML.
- How would you design an ML strategy to increase revenue for our business?
- What are your thoughts on improving our current data pipeline?
- How do you define and measure the success of an ML project?
- What’s the most impactful ML project you’ve worked on, and what were your key learnings?
01What is the career path for Machine Learning Engineers?
Machine Learning offers one of the most rewarding and fast-growing career paths in tech. Here’s how your career could evolve — from your first role to advanced leadership positions — along with average annual salaries at top tech companies. 1. ML Engineer / Applied Scientist I (Entry-Level)
Experience: 0–2 years Typical Roles:
- Machine Learning Engineer
- Applied Scientist
- Data Scientist (ML-focused)
Skills Required: Python, data structures & algorithms, basic ML algorithms, supervised/unsupervised learning, model training & evaluation
Average Salary (MAANG+): $130K – $180K base + bonuses + stock 2. ML Engineer II / Research Engineer / Applied Scientist II
Experience: 2–4 years
Typical Roles:
- Mid-level ML Engineer
- Applied Scientist II
- ML Research Engineer
Skills Required: End-to-end ML pipelines, deep learning, production deployment, MLOps, scalable system design
Average Salary (MAANG+): $170K – $250K base + performance bonus + equity 3. Senior ML Engineer / Senior Applied Scientist
Experience: 4–7 years
Typical Roles:
- Senior ML Engineer
- Senior Data Scientist (AI/ML focus)
- Lead Applied Scientist
Skills Required: ML system design, optimization at scale, advanced modeling (transformers, GANs, RL), mentoring juniors, cross-team collaboration
Average Salary (MAANG+): $220K – $350K total comp (can go higher with equity) 4. Staff ML Engineer / Principal Scientist / Tech Lead
Experience: 7–10 years
Typical Roles:
- Staff ML Engineer
- Machine Learning Tech Lead
- Principal Applied Scientist
Skills Required: Technical leadership, architecting ML platforms, model lifecycle management, stakeholder communication, team mentoring
Average Salary (MAANG+): $300K – $500K+ total compensation 5. ML Engineering Manager / Director of ML
Experience: 10+ years
Typical Roles:
- Engineering Manager (ML Team)
- Director / VP of AI/ML
Skills Required: People management, strategic planning, roadmap ownership, aligning ML initiatives with business goals
Average Salary (MAANG+): $400K – $800K+ total compensation